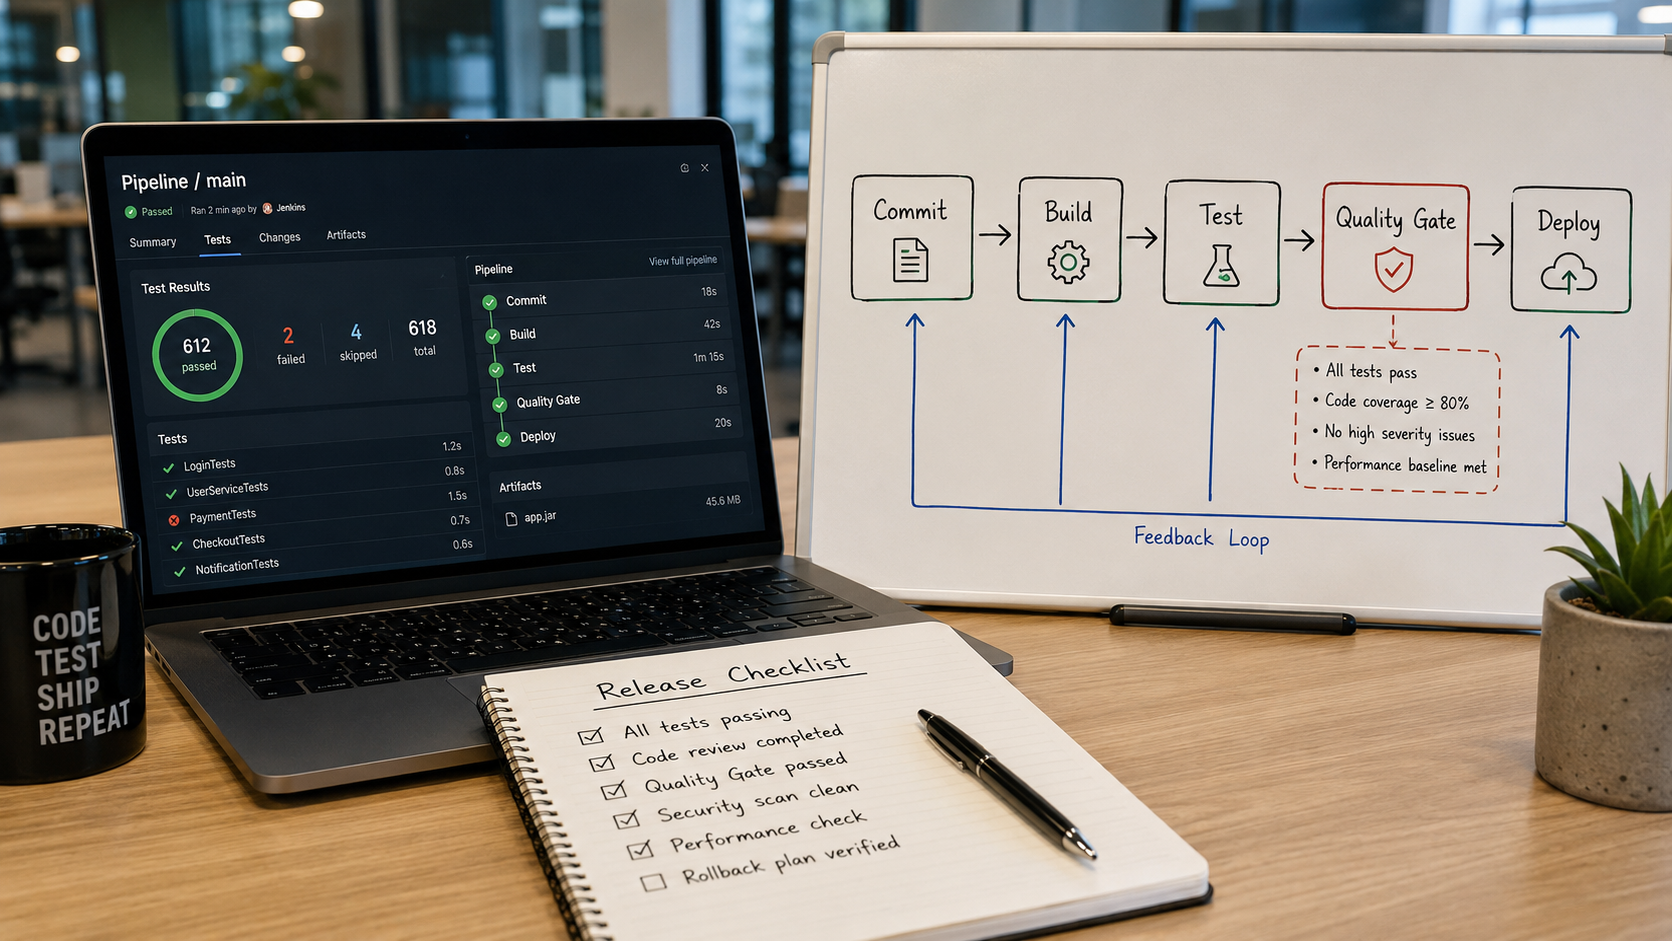
When people first learn CI/CD pipelines, we usually explain them like this:
Build
  ↓
Test
  ↓
Deploy
Simple.
And technically, there is nothing wrong with that.
But the more I look at pipelines from a Quality Engineering point of view, the more I think this description is too small.
A pipeline is not just a mechanism for moving code from one environment to another.
For me, a good pipeline is actually a series of automated quality decisions.
At every stage, the system should be asking:
Is this change healthy enough to move forward?
That is where pipelines become much more interesting.
A pipeline is really a decision flow
Imagine a normal software change.
A developer commits some code.
The pipeline starts.
Most people see this:
Commit
  ↓
Build
  ↓
Test
  ↓
Deploy
I prefer to see this:
Code committed
      ↓
Can it build?
      ↓
Did unit tests pass?
      ↓
Did static checks pass?
      ↓
Did API tests pass?
      ↓
Can it deploy safely to test?
      ↓
Did end-to-end tests pass?
      ↓
Do we have enough evidence?
      ↓
Can this move to production?
That is very different.
The first version is automation.
The second version is quality control built into delivery.
Every stage should answer a question
This is the way I would explain pipelines to somebody learning Azure DevOps.
Do not start with YAML.
Start with questions.
For example:
BUILD
Question:
Can the application compile and package successfully?
Then:
UNIT TESTS
Question:
Did the basic logic survive this change?
Then:
STATIC / SECURITY CHECKS
Question:
Did we introduce an obvious code or security risk?
Then:
API TESTS
Question:
Are the main service contracts and business rules still behaving correctly?
Then:
DEPLOY TO TEST
Question:
Can this version actually run in a realistic environment?
Then:
E2E TESTS
Question:
Can a real user journey still work end to end?
Then:
APPROVAL / GATE
Question:
Do we have enough confidence to move this further?
Now the pipeline has meaning.
It is no longer a collection of technical steps.
It becomes evidence moving through a system.
Build failures are easy
Some pipeline decisions are simple.
If the build fails:
STOP
No debate.
If unit tests fail:
STOP
Again, straightforward.
But quality becomes more interesting when the answer is not binary.
Imagine:
Build              PASS
Unit Tests         PASS
API Tests          PASS
E2E Tests          PASS
Security Scan      WARNING
Performance        DEGRADED
Flaky Tests        INCREASED
Now what?
Should the deployment continue?
Should somebody review it?
Should only production be blocked?
Should it be allowed into staging?
That is where pipeline design starts becoming a Quality Engineering problem rather than just a DevOps problem.
Not every failure should be treated equally
This is something I think is important.
Suppose one low-risk UI test fails because a selector changed.
Compare that with:
Payment API regression failed.
They are both technically test failures.
But they do not carry the same business risk.
A good pipeline should reflect that.
Maybe:
Critical API test fails
        ↓
BLOCK
but:
Known flaky non-critical test fails
        ↓
ALLOW WITH WARNING
        ↓
Create investigation
The exact rule will depend on the system.
The important thing is that the pipeline should not blindly treat every signal as equal.
Quality gates should be risk-based.
Azure DevOps stages make this easier to structure
This is where Azure DevOps becomes useful.
Instead of building one massive job with fifty steps, we can break the pipeline into stages.
Conceptually:
stages:

- stage: Build
- stage: UnitTests
- stage: ApiTests
- stage: DeployTest
- stage: E2ETests
- stage: DeployProduction
Now each stage has a purpose.
Azure DevOps stages are useful logical boundaries in a pipeline. They can represent things such as building the application, running tests, or deploying to pre-production.
This is much cleaner than thinking of the pipeline as one long script.
Stage → Job → Step
This is probably the first Azure DevOps structure worth understanding.
Think of it like this:
Pipeline
   ↓
Stage
   ↓
Job
   ↓
Step
For example:
Pipeline: Web Application

Stage: Test
   ↓
Job: API Tests
   ↓
Step 1: Install dependencies
Step 2: Start test environment
Step 3: Run tests
Step 4: Publish results
That structure helps keep pipelines readable.
And readable pipelines matter.
If only one person understands the YAML, that is already a risk.
Publishing test results matters
Running tests inside a pipeline is useful.
But simply printing this:
87 tests passed
2 tests failed
into a build log is not enough for me.
Test results should become visible evidence.
Azure Pipelines can publish test results so they can be reviewed directly in the pipeline rather than being buried in console output. Microsoft currently supports publishing results from common test formats through the PublishTestResults@2 task.
For example:
- task: PublishTestResults@2
  inputs:
    testResultsFormat: 'JUnit'
    testResultsFiles: '**/results.xml'
Now we have something people can actually inspect.
That means the pipeline is not only saying:
FAILED
It is also helping us understand:
Which tests failed?

How many?

What was the trend?

Was this new?

Was this flaky?
That is much more useful.
A pipeline should produce evidence, not just logs
This is a principle I like.
Pipeline output
      ↓
Not just:
"Something failed."

But:
"What failed?"
"Where?"
"How serious?"
"What evidence do we have?"
That evidence might include:
Test results
Coverage
Security findings
Artifacts
Logs
Screenshots
Trace files
Performance results
Deployment information
When a pipeline produces useful evidence, investigation becomes faster.
And release decisions become better.
Azure environments are more than environment names
When I first looked at environments, it was easy to think of them simply as:
DEV
TEST
UAT
PROD
But in Azure DevOps, an environment can represent the logical target where software is deployed, such as Dev, Test, QA, Staging, or Production.
That gives us another useful control point.
For example:
Deploy Test
      ↓
Run regression
      ↓
Deploy Staging
      ↓
Approval
      ↓
Deploy Production
Now the environment becomes part of the governance model.
Not just somewhere the application happens to run.
Human approval still has a place
I am a big supporter of automation.
But I do not think every production deployment should automatically happen just because the previous stage turned green.
There are situations where human approval still makes sense.
Azure DevOps supports approvals and checks for environments, and these can be used to control when a stage is allowed to proceed, particularly around production deployment.
For example:
Build        PASS
Tests        PASS
Security     PASS
Deploy Test  PASS
Regression   PASS
        ↓
Production Approval
        ↓
Deploy
This is not anti-automation.
It is risk management.
There may be business timing to consider.
A release window.
A known production issue.
An infrastructure dependency.
A customer event.
A rollback concern.
Automation can tell us the technical state.
A human may still need to consider context.
Quality gates should stop bad changes early
One thing I really like about pipelines is this:
Bad news can arrive quickly.
Imagine finding a major API regression after three days of manual testing.
Now compare that with:
Developer commits code
        ↓
6 minutes later
        ↓
API regression detected
        ↓
Pipeline stopped
That is powerful.
The earlier we detect the issue, the cheaper it usually is to fix.
This is where automation creates real value.
Not because we have “more tests.”
Because feedback arrives when it is still useful.
Do not push every test into the same stage
Another mistake is trying to run everything everywhere.
For example:
10,000 tests
on every commit
That sounds thorough.
It can also make pipelines painfully slow.
Then developers stop trusting them.
Or start avoiding them.
A better approach may be something like:
Pull Request

Build
Unit Tests
Critical API Tests
Static Checks
Then:
Main Branch

Full API Regression
Integration Tests
Deploy Test
E2E Tests
Then perhaps:
Nightly

Large Regression
Cross-browser
Performance
Long-running tests
Different tests serve different feedback needs.
Fast feedback should stay fast.
Flaky tests become a pipeline problem
A flaky test is not only a test automation problem.
Once it sits inside CI/CD, it becomes a delivery problem.
Imagine:
Pipeline failed.

Reason:
Test XYZ failed.

Retry:
PASS.
Again tomorrow:
FAIL.

Retry:
PASS.
Very quickly people learn:
Ignore XYZ.
Then eventually XYZ fails because of a real defect.
Nobody believes it.
That is dangerous.
Azure Pipelines includes support for identifying and managing flaky tests, which is useful because unreliable tests reduce confidence in pipeline results.
For me:
A quality gate is only useful
if people trust the signal.
Playwright fits naturally into this model
For web applications, Playwright can sit very naturally in the later testing stages.
Something like:
Build
   ↓
Unit Tests
   ↓
Deploy Test Environment
   ↓
Playwright
   ↓
Publish Results
Azure's Playwright tooling supports continuous end-to-end testing in CI workflows including Azure Pipelines.
A simplified pipeline might look like:
- script: npm ci
  displayName: Install dependencies

- script: npx playwright install --with-deps
  displayName: Install Playwright browsers

- script: npx playwright test
  displayName: Run Playwright tests
Then publish the results.
The YAML itself is not the interesting bit.
The interesting bit is deciding:
Which Playwright tests run here?

What happens if one fails?

Do we publish screenshots?

Do we retain traces?

Does this block production?
That is pipeline design.
The pipeline should tell us whether we can move forward
This is probably the simplest way I think about it.
Every pipeline stage should answer:
YES
NO
or
WE NEED A HUMAN DECISION
For example:
Can we build?
YES

Did critical tests pass?
YES

Did security checks pass?
YES

Is the test environment healthy?
YES

Did regression pass?
YES

Are there unresolved risks?
REVIEW

Can we deploy production?
APPROVAL
That is much more meaningful than:
Pipeline run #3842 succeeded.
Pipelines also create governance
There is another important benefit.
A well-designed pipeline makes the delivery process repeatable.
Without that, releases can become:
Someone builds locally.

Someone copies something.

Someone runs some tests.

Someone remembers another check.

Someone deploys.
Hopefully everything was done.
A pipeline turns that into:
Same process.
Every time.
Visible evidence.
Clear outcome.
That is governance without creating a fifty-page process document.
The process is executable.
Reusable templates become important as teams grow
Once multiple applications use Azure DevOps, copying the same YAML everywhere becomes difficult to maintain.
For example:
Repo A
azure-pipelines.yml

Repo B
azure-pipelines.yml

Repo C
azure-pipelines.yml

Repo D
azure-pipelines.yml
Then somebody updates the security step.
Now four pipelines need changing.
This is where reusable templates become important.
Conceptually:
Shared Build Template
Shared Test Template
Shared Security Template
Shared Deployment Template
Applications then reuse the common patterns.
That gives consistency.
And consistency makes governance much easier.
Secrets do not belong in YAML
Another basic but very important rule.
Do not do this:
password: myProductionPassword123
Never.
Secrets should be handled through appropriate secure mechanisms such as secret variables, variable groups, Key Vault integration, service connections, managed identities, or service principals depending on the use case.
Azure DevOps supports service principals and managed identities for authentication scenarios, reducing the need to rely on personal credentials.
A pipeline should automate delivery.
It should not create a security problem while doing it.
What should actually block production?
This is probably one of the best conversations a team can have.
Ask:
What conditions must be true
before production deployment is allowed?
For example:
Build successful
Critical unit tests passed
Critical API tests passed
No critical security issue
E2E smoke tests passed
Deployment artifact produced
Production approval completed
Now the release standard is visible.
Not hidden in somebody's memory.
Not dependent on who is doing the release.
Visible.
Repeatable.
Auditable.
My view
I think people sometimes make CI/CD sound more complicated than it needs to be.
At the beginning, it can simply be:
Commit
  ↓
Build
  ↓
Test
  ↓
Deploy
That is enough to start learning.
Then gradually add maturity.
Commit
  ↓
Build
  ↓
Unit Tests
  ↓
Static / Security Checks
  ↓
API Tests
  ↓
Deploy to Test
  ↓
E2E Tests
  ↓
Publish Evidence
  ↓
Quality Gate
  ↓
Approval
  ↓
Production
The important part is not creating the biggest pipeline.
The important part is knowing why each stage exists.
For me, that is where Quality Engineering and DevOps meet.
Quality should not be something we check after software has been built.
The delivery process itself should continuously ask:
Do we have enough evidence to move forward?
And once you start looking at pipelines that way, Build → Test → Deploy feels very different.
It becomes:
Build → Evaluate → Learn → Decide → Move Forward.
That is the pipeline mindset I find much more useful.